The answers in your PDFs, found and put to work.
Spec sheets, supplier catalogs, and manuals become content your team and your AI can search and use, so reps and service agents find the right answer in seconds instead of scrolling through PDFs.
Document Intelligence is part of Pimly Product Intelligence and works two ways: inside Vera, where you attach a document and put it to work, and directly on the digital assets you already store in Pimly.
Document Intelligence is part of Pimly Product Intelligence and works two ways: inside Vera, where you attach a document and put it to work, and directly on the digital assets you already store in Pimly.
Book a Demo
Find any document by what's inside it.
Today, people hunt for the right manual by file name and folder, open five PDFs, and hope one is current.
Set an Indexing Strategy on a digital asset once, and Pimly reads the PDF in the background and adds its contents to your search index. Searches find manuals and spec sheets by what they say, including tables and scanned pages. It runs on its own, with no chat involved, and never changes your product records.
Set an Indexing Strategy on a digital asset once, and Pimly reads the PDF in the background and adds its contents to your search index. Searches find manuals and spec sheets by what they say, including tables and scanned pages. It runs on its own, with no chat involved, and never changes your product records.

Supplier catalogs become approved product updates.
Rekeying a supplier catalog is one of the slowest jobs in product data. Someone reads every page and types specs in one field at a time.
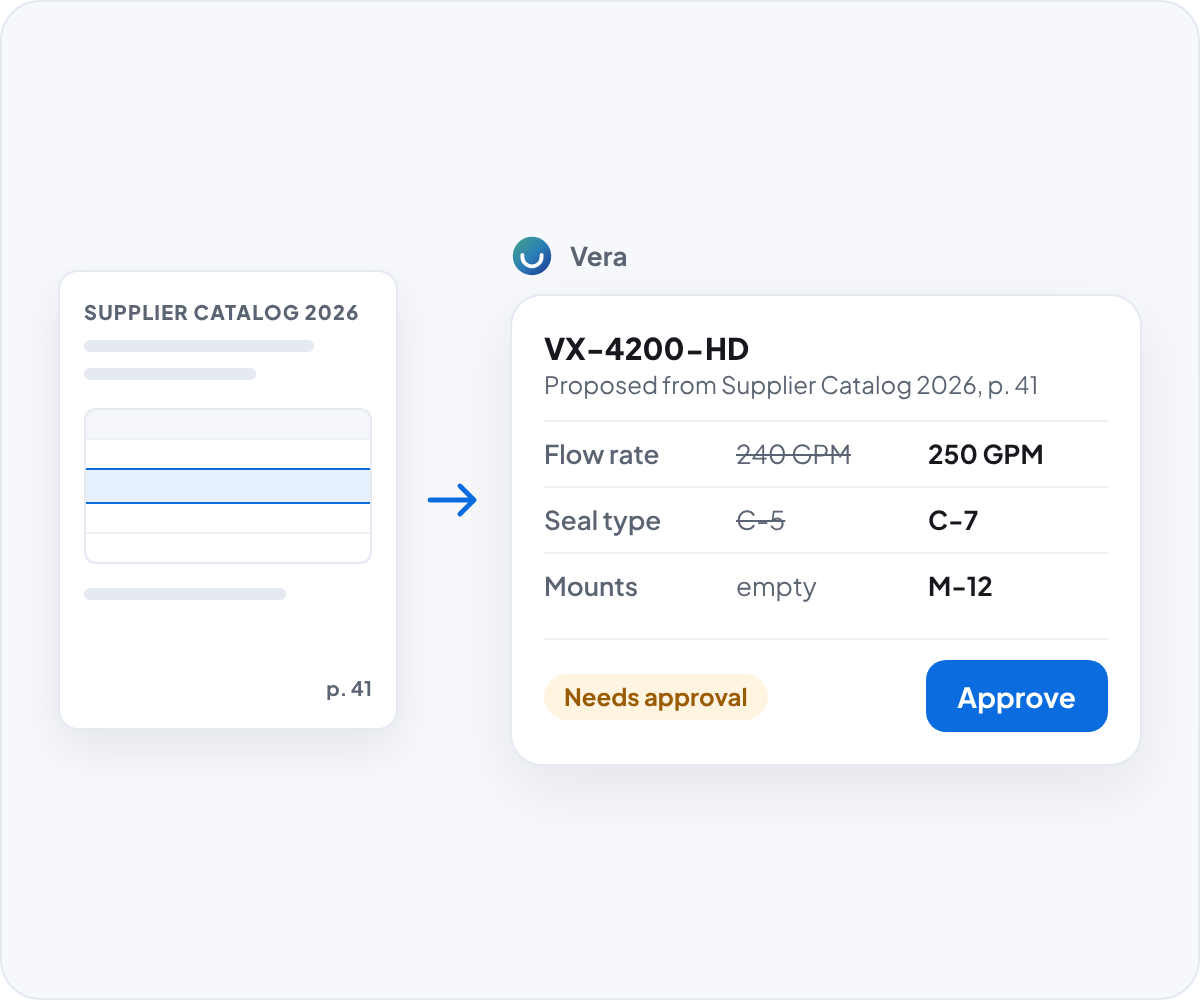
Attach the catalog in Vera and ask her to update the matching products. She reads the relevant pages and tables and proposes the changes. Nothing is written until a person approves the preview, and every change lands in the audit trail.
Attach the catalog in Vera and ask her to update the matching products. She reads the relevant pages and tables and proposes the changes. Nothing is written until a person approves the preview, and every change lands in the audit trail.
Answers straight from the spec sheet.
Answering "what's the maximum operating temperature?" shouldn't mean opening a PDF and scrolling.
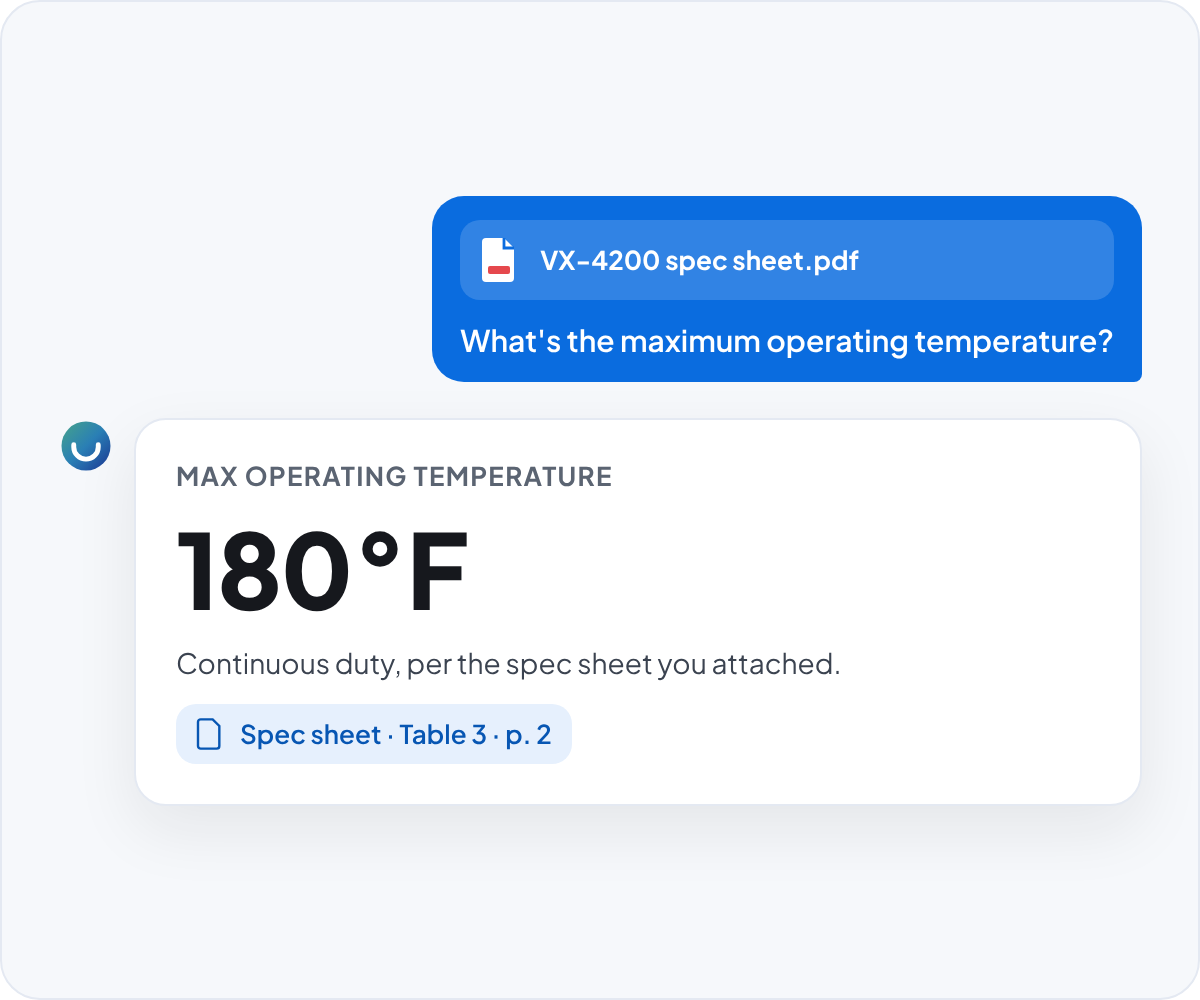
Attach the document in Vera and ask. She reads the right section, page range, or table and answers from the document you gave her, not from general knowledge. Pimly reads each document once and keeps a structured version, so attaching the same file again doesn't mean reading it all over.
Attach the document in Vera and ask. She reads the right section, page range, or table and answers from the document you gave her, not from general knowledge. Pimly reads each document once and keeps a structured version, so attaching the same file again doesn't mean reading it all over.
The right reading level for every document.
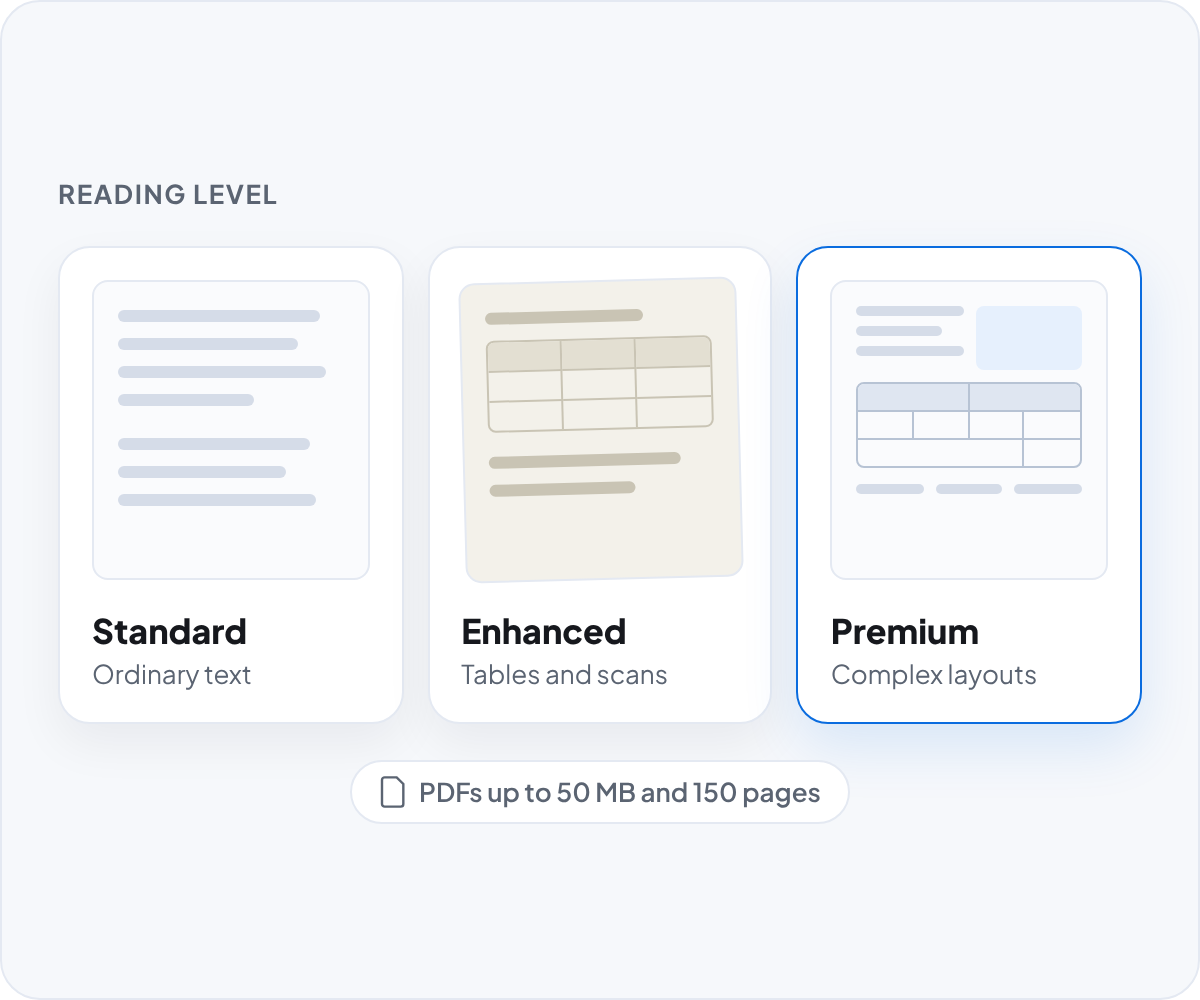
Standard reads ordinary text documents. Enhanced handles tables and scanned documents. Premium handles complex layouts and merged cells. You choose the level that fits each document.
Images can be indexed too, so they can be found by visual search. PDFs up to 50 MB and 150 pages are supported today. Vera also reads small CSV, text and similar files today, with support for larger files coming soon.
Images can be indexed too, so they can be found by visual search. PDFs up to 50 MB and 150 pages are supported today. Vera also reads small CSV, text and similar files today, with support for larger files coming soon.
Your documents stay yours
Encrypted and private
Documents are encrypted at rest and filed under your org, never shared with other customers. Uploaded files are deleted after 90 days.
Never used for training
Your documents are never used to train AI models, by Pimly or by the services that help read them.
A person approves every change
Document Intelligence never updates products on its own. Vera proposes changes from a document, and a person approves each one before anything is written.
See Document Intelligence work on your own spec sheets.
Book a Demo
Frequently Asked Questions
PDFs up to 50 MB and 150 pages. Vera also reads small CSV, TSV, text, Markdown, JSON and HTML files today, and support for larger files of those types is coming soon. Excel and Word files aren't supported yet.
Yes. Standard reads ordinary text documents, Enhanced handles tables and scanned pages, and Premium handles complex layouts and merged cells. You choose the level that fits each document.
No. Asset indexing only updates the asset's indexing status. When Vera proposes product updates from a document, a person approves every change before anything is written.
Documents are processed securely by Pimly and the services that help read them, under no-training agreements. They stay filed under your org and are never used to train AI models.
Uploaded PDFs are kept for 90 days and their readable versions for up to a year. Content indexed from digital assets stays in the search index as long as the asset exists. Everything is encrypted at rest and filed under your org.
Book a demo and we'll set up Document Intelligence around your documents and use case. Once it's on, you set an Indexing Strategy on your assets or attach PDFs in Vera.